Biology · Unit 4: DNA and inheritance
DNA: Structure and Copying
How can a cell copy about six billion base pairs of DNA and make almost no mistakes? You build DNA from its parts, unzip it and copy it in a simulation, then test the base-pairing rule against real base counts from seven kinds of living things. Afterwards you can describe a nucleotide and the double helix, explain the steps of copying, and use base data to support the A with T, C with G rule.
Where this lesson sits
- Virginia SOL BIO.5a
- Practices BIO.1c, BIO.1d, BIO.1e, BIO.1f
Essential question: How does the structure of DNA let it store information and copy itself almost perfectly?
-
Life Science (grade 7) LS.10 a
Review it at grade 7 level
In Life Science you learned that DNA is shaped like a twisted ladder called a double helix. The sides of the ladder are made of sugar and phosphate, and they are the same in all living things. The rungs are pairs of bases, written A, T, C and G. The order of the bases forms a code for making proteins, and a gene is a section of a chromosome that carries the code for one protein. Chromosomes are strands of tightly wound DNA. Biology adds how the cell copies DNA before it divides, and why copying is so accurate.
-
Biology BIO.5a You are here
This lesson
-
Biology II Biology II: Genetics, GEN.2 a
Preview where it goes next
The Biology II Genetics course names the ends of each strand: one is the 5′ end and the other the 3′ end, and the two strands are antiparallel. DNA polymerase can only add a nucleotide to the 3′ end of a growing strand, so new DNA always grows 5′ to 3′. Helicase unwinds the helix at the replication fork, and an RNA primer gives polymerase a starting end. One new strand, the leading strand, grows smoothly toward the fork. The other, the lagging strand, is made in short Okazaki fragments that DNA ligase seals together. Replication is called semiconservative because each daughter molecule keeps one parent strand. The course also asks how a system this accurate still leaves room for the rare changes that evolution acts on.
-
College
Watch first Base Pairing Lets DNA Copy Itself · 3:03
A typical human cell with a nucleus holds nearly 2 metres of DNA, packed into a nucleus only about 0.005 to 0.010 millimetres across. Before a typical cell divides, it copies roughly 6 billion base pairs of that DNA and gets almost every one right. Two metres is taller than most adults. How can a molecule that long fit in a space you cannot see without a microscope? And how can a cell copy it so accurately, again and again?
What do you think? Decide before you read.
-
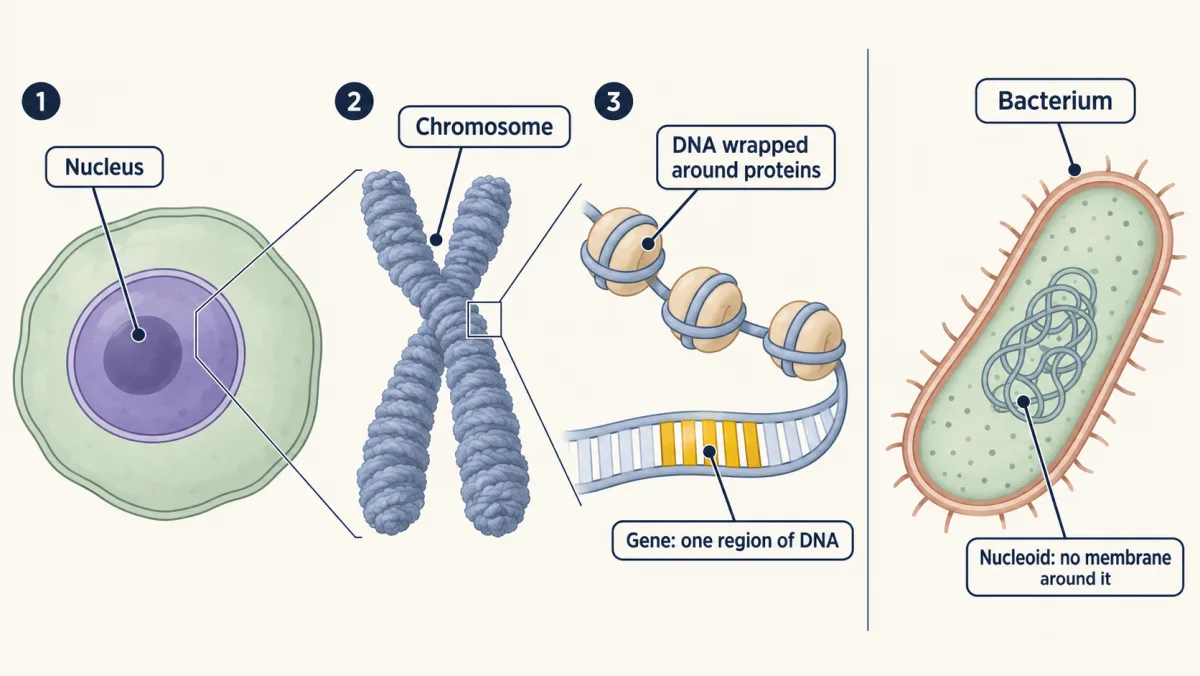
Scientists disagree: Bacteria have DNA too. In a bacterium such as E. coli, the DNA sits in a region called the nucleoid, with no membrane around it. Microscopes and chemical tests find DNA in every kind of cell that grows and divides. A few specialized cells, such as mature human red blood cells, lose their nucleus as they mature.
What scientists think
Scientists disagree: Bacteria have DNA too. In a bacterium such as E. coli, the DNA sits in a region called the nucleoid, with no membrane around it. Microscopes and chemical tests find DNA in every kind of cell that grows and divides. A few specialized cells, such as mature human red blood cells, lose their nucleus as they mature.
-
Scientists disagree: A chromosome is one very long DNA molecule wrapped with proteins. A gene is one region along that DNA. Scientists who read the order of bases along human chromosomes find that each chromosome carries many genes, often hundreds or more, with other DNA between them.
What scientists think
Scientists disagree: A chromosome is one very long DNA molecule wrapped with proteins. A gene is one region along that DNA. Scientists who read the order of bases along human chromosomes find that each chromosome carries many genes, often hundreds or more, with other DNA between them.
-
Scientists disagree: When scientists read the whole human genome (all of a person’s DNA), only about 1 to 2 percent of it turned out to code for proteins. Some of the rest controls when and where genes are switched on. Some codes for RNA molecules that do jobs of their own. For much of it, nobody knows the job yet.
What scientists think
Scientists disagree: When scientists read the whole human genome (all of a person’s DNA), only about 1 to 2 percent of it turned out to code for proteins. Some of the rest controls when and where genes are switched on. Some codes for RNA molecules that do jobs of their own. For much of it, nobody knows the job yet.
Explore: unzip and copy a DNA molecule
The simulation shows a short piece of DNA as two rows of labelled blocks, one block for each base. You unzip the two strands one step at a time and drop matching nucleotides into place on each open strand. A “mistake” button slips in a wrong base so you can watch what happens to it. At the end you see what has been built.
Solid block = old strand. Outlined block = new strand. Short line = a base pair. ✕ = a mismatch.
In this sketch: 6 base pairs stand in for the roughly 6 billion a cell copies. Flat blocks stand for the twisted double helix. Real DNA strands run in opposite directions and one new strand is built in short pieces; here both are filled in left to right to keep the sketch simple. Proofread always removes a wrong base.
Rule to keep: A pairs with T and C pairs with G, so each old strand sets the order of its new partner. The copy is two identical molecules, each with one old strand and one new strand. In a cell, proofreading removes most wrong bases, and a textbook estimate is about one uncorrected mistake for every billion bases copied.
Try this.
- Before you start, predict how many DNA molecules you will have at the end, and which strands each one will contain. Then copy the whole piece.
- Pick one open strand and predict the base that must pair with each block before you drop it in. Test your predictions one at a time.
- Press the mistake button. Predict whether the finished molecules will still match, then watch the mismatch and what the simulation does with it.
- Compare the two finished molecules with the original. Predict which bases will differ, then check every pair.
Explain: a twisted ladder of four bases
- nucleotide
- base
- double helix
- covalent bond
- hydrogen bond
- base pairing
- gene
- chromosome
- replication
- template
- enzyme
- nucleoid
DNA is a polymer, a long chain built from small repeating units. Each unit is a nucleotide, a building block made of three parts: a sugar called deoxyribose, a phosphate group and a base. A base is the part of a nucleotide that carries information, and DNA uses four of them: adenine (A), thymine (T), cytosine (C) and guanine (G). Nucleotides are named by their base, so you will hear about “an A” or “a G.”
Along one strand, the sugar of one nucleotide is joined to the phosphate of the next by a covalent bond, a strong bond in which atoms share electrons. That makes a sugar-phosphate backbone with the bases sticking out to one side.
Two strands line up with their bases facing each other in the middle. A hydrogen bond is a weak attraction between molecules or parts of molecules, and hydrogen bonds hold each pair of facing bases together. The two strands then twist around each other into a double helix, a shape like a ladder twisted along its length. The backbones are the sides of the ladder, and the base pairs are the rungs.
Base pairing is the rule that A always pairs with T and C always pairs with G across the two strands. Picture a zipper whose teeth only close with the right partner. The analogy breaks because a zipper’s teeth carry no message, while the order of DNA’s bases does.
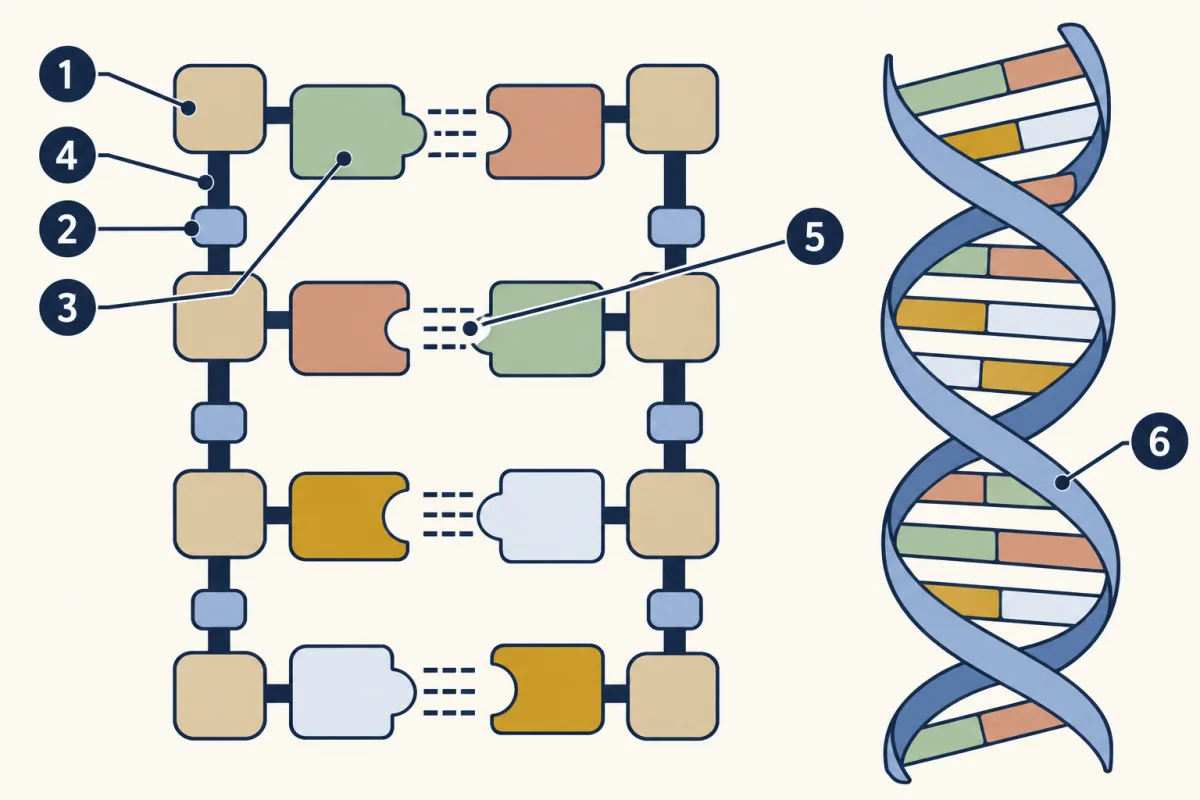
- sugar
- phosphate
- base
- covalent bond
- hydrogen bond
- double helix
- sugar
- blank
- blank
- blank
- blank
- double helix
Word bank: base, covalent bond, hydrogen bond, phosphate
- blank
- blank
- blank
- blank
- blank
- blank
Check your labels
- sugar
- phosphate
- base
- covalent bond
- hydrogen bond
- double helix
The two strands also run in opposite directions, like two lanes of a road. Each strand has a distinct “head” end and “tail” end, and the strands lie head to tail.
The order of the bases is the information. A gene is a region of DNA whose base order, in most genes, codes for a protein; a few genes code for RNA molecules that do jobs of their own. A chromosome is one very long DNA molecule wrapped around proteins, and it carries many genes. Only about 1 to 2 percent of human DNA codes for proteins. Other stretches control genes, help hold chromosomes in shape, or have jobs nobody has found yet. The genetic code that turns base order into protein is almost the same in every living thing, which is why bacteria can be engineered to make some human proteins, such as insulin. From DNA to protein shows how that code is read.
Every cell that grows and divides carries DNA. In plants, animals and fungi most of it sits inside the nucleus, with small extra pieces in organelles such as mitochondria. Bacteria keep their DNA in a nucleoid, a region of the cell with no membrane around it.
Explain: copying DNA one strand at a time
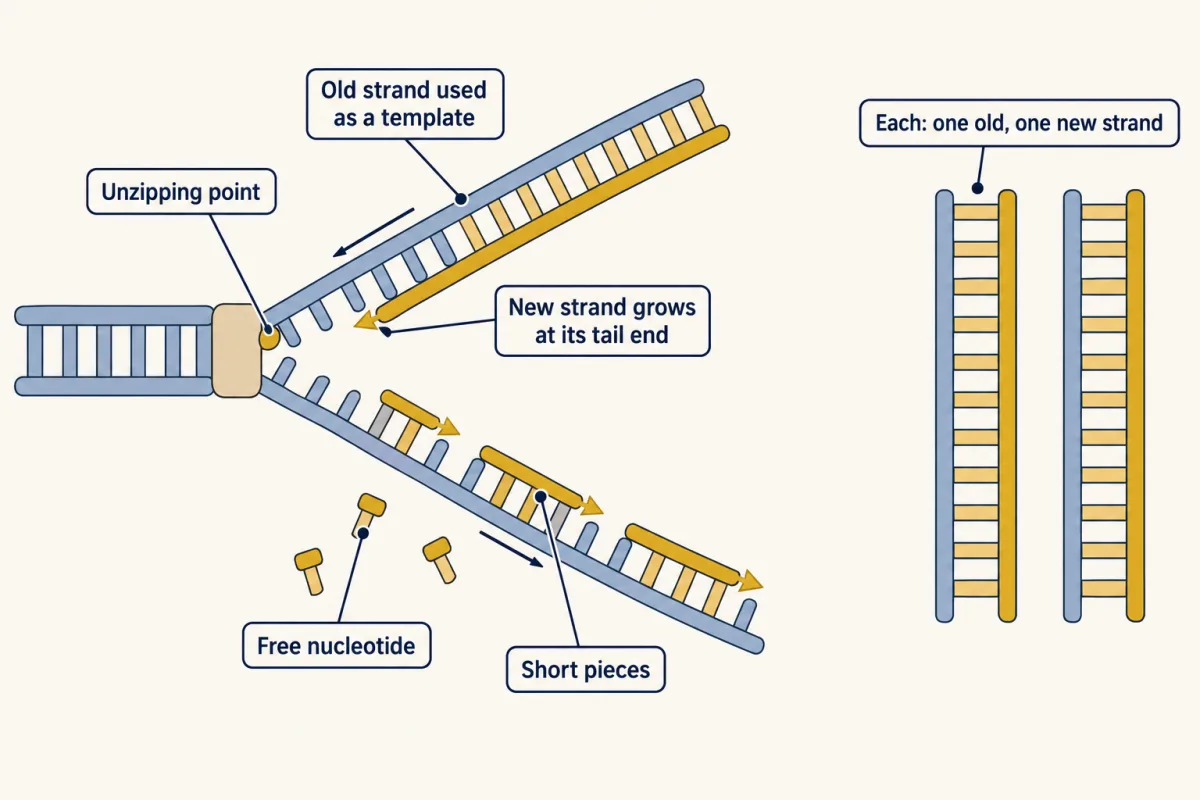
Replication is the copying of a DNA molecule before a cell divides. Because A must pair with T and C with G, each strand carries everything needed to rebuild its partner. Each old strand works as a template, a pattern that sets the order of the new strand.
Copying is done by enzymes. An enzyme is a protein that speeds up a chemical reaction without being used up. The steps, in order:
- An enzyme unwinds the helix and unzips it, breaking the hydrogen bonds between the base pairs. The covalent backbones stay whole.
- Free nucleotides float nearby in the cell. Each one pairs with its matching base on an open strand: A with T, C with G.
- Another enzyme, DNA polymerase, joins the new nucleotides into a strand with covalent bonds.
- The result is two DNA molecules. Each has one old strand and one new strand, and both have the same base order as the original.
Why only one direction? DNA polymerase can attach a new nucleotide only to one particular end of a growing strand, the tail end. So every new strand grows the same way, adding at its tail. The two templates point in opposite directions. One new strand can grow smoothly toward the unzipping point. The other grows away from the unzipping point, so it must be built in short pieces, each started fresh as more template opens up. Another enzyme then joins the pieces.
How close to “almost perfect” is it? DNA polymerase checks each new base and removes most wrong ones, a step called proofreading. Repair enzymes catch many errors that slip past. A textbook estimate is about one uncorrected mistake for every billion bases copied. Across roughly 6 billion base pairs, that leaves roughly a handful to a dozen changes per copy. Those rare changes are mutations, and mutations can change proteins.
Elaborate: do the bases really pair up?
If A always pairs with T, a sample of double-stranded DNA should hold as much A as T, and as much G as C. Here is base-composition data in the style of Erwin Chargaff’s measurements from around 1950.
| Organism (label as printed) | A (% of bases) | T (% of bases) | G (% of bases) | C (% of bases) |
|---|---|---|---|---|
| Human | 29.3 | 30.0 | 20.7 | 20.0 |
| Chicken | 28.0 | 28.4 | 22.0 | 21.6 |
| Grasshopper | 29.3 | 29.3 | 20.5 | 20.7 |
| Sea urchin | 32.8 | 32.1 | 17.7 | 17.3 |
| Wheat | 27.3 | 27.1 | 22.7 | 22.8 |
| Yeast | 31.3 | 32.9 | 18.7 | 17.1 |
| E. coli | 24.7 | 23.6 | 26.0 | 25.7 |
Source: a representative sample of Chargaff’s 1952 data as reprinted in a review (Bansal, Current Science 85:1556-1563, 2003, Table 1) and in the Wikipedia table “Chargaff’s rules” that cites it. We could not open Chargaff’s original papers, so treat each row as an example. Rows are measured averages, so some do not add to exactly 100.
- In each row, how far apart are A and T? How far apart are G and C? Which row has the biggest gap?
- Add A and T for the E. coli row and for the sea urchin row. How different are they?
- Does any organism have all four bases at 25 percent?
Claim, evidence, reasoning
Make a claim that answers the essential question: does this base data support the rule that A pairs with T and C pairs with G across the two strands of DNA?
Start with: The data blank the base-pairing rule, because in every organism blank.
Start with: In the blank row, A is blank % and T is blank %, and G is blank % and C is blank %. A plus T ranges from blank % in blank to blank % in blank.
Start with: If every A on one strand sits across from a T on the other, then blank. The mix of pairs can still differ between species because blank.
Compare with a model answer
The data support the base-pairing rule. In every row, A is within about 1.6 percentage points of T, and G is within about 1.6 points of C. In humans, A is 29.3 % and T is 30.0 %; G is 20.7 % and C is 20.0 %. If every A sits across from a T, a double strand must hold equal amounts of the two. The total of A plus T still changes, from about 48 % in the E. coli row to about 65 % in the sea urchin, because the rule fixes the partners, not how many of each pair a species has. But this is one teaching table with unknown samples, and base counts cannot show the helix.
Saved in this browser only.
Design problem
Every cell in an animal’s body grows from one fertilized egg by copying DNA. Plan an investigation to test whether DNA from different tissues of one animal has the same base composition, and whether it differs from another species.
One way to do it
- Question and hypothesis: If cells copy their DNA accurately, then liver and muscle DNA from the same chicken will have the same percentages of A, T, G and C, while wheat DNA will differ.
- Independent variable: the tissue (chicken liver, chicken muscle) and the species (chicken, wheat).
- Dependent variable: the percentage of each base, measured by a lab that sequences the DNA and counts every base.
- Constants: the same DNA extraction method, the same lab and machine, the same counting software.
- Control: a DNA sample whose base percentages are already known, run alongside to check the method.
- Repeated trials and sample size: tissue from at least three chickens and three wheat plants, each measured twice, then a mean for each tissue and species.
- Ethics and safety: use tissue from chickens already sold for food, so no animal is harmed for the study, and wear gloves around raw meat.
If the two chicken tissues differ from each other by no more than repeated measurements of the same sample differ, and wheat differs by more, the hypothesis is supported. A large difference between chicken tissues would point to a problem with the samples or the method before anything else.
Evaluate: check your thinking
The 2 metres of DNA fit because the molecule is extremely thin and is wound tightly around proteins. The near-perfect copying comes from the structure itself. Each strand is a template for the other, base pairing allows only one correct partner at each spot, and proofreading removes most of the rare mistakes.
Science practices you used: making predictions and testing them with a model, naming where a model or analogy breaks, reading a data table and comparing values, making a claim from evidence with reasoning, and planning an investigation with controls and repeated trials.
How we measure it
Base-composition analysis
DNA is purified from a sample and broken down into its bases, and the amount of each base is measured as a percentage of all the bases. Comparing those percentages across species is how scientists found that A matches T and G matches C.
DNA sequencing
A sequencing machine reads the order of bases along DNA, and computers join the short stretches it reads into whole chromosomes. Sequencing is how we know the size of the human genome and how much of it codes for protein.
Finish line
Test yourself
8 questions
Practice and MCAT-style, with explained answers.
Next · Lesson 17
How the DNA Model Was Built
Reading the first human genome took a project of about 13 years, and by 2022 the estimated cost to sequence a human-sized genome was about $525. What changed?
Continue →